Data Engineering/2024
Signal / Data quality pipeline
An inspectable ingestion pipeline that treats data contracts and recovery as product features.
Illustrative case study, not a claim of client work or measured production outcomes.
Concept case study. Demo and repository links are intentionally omitted; replace this content with your own verifiable project and public links.
Context
Overview
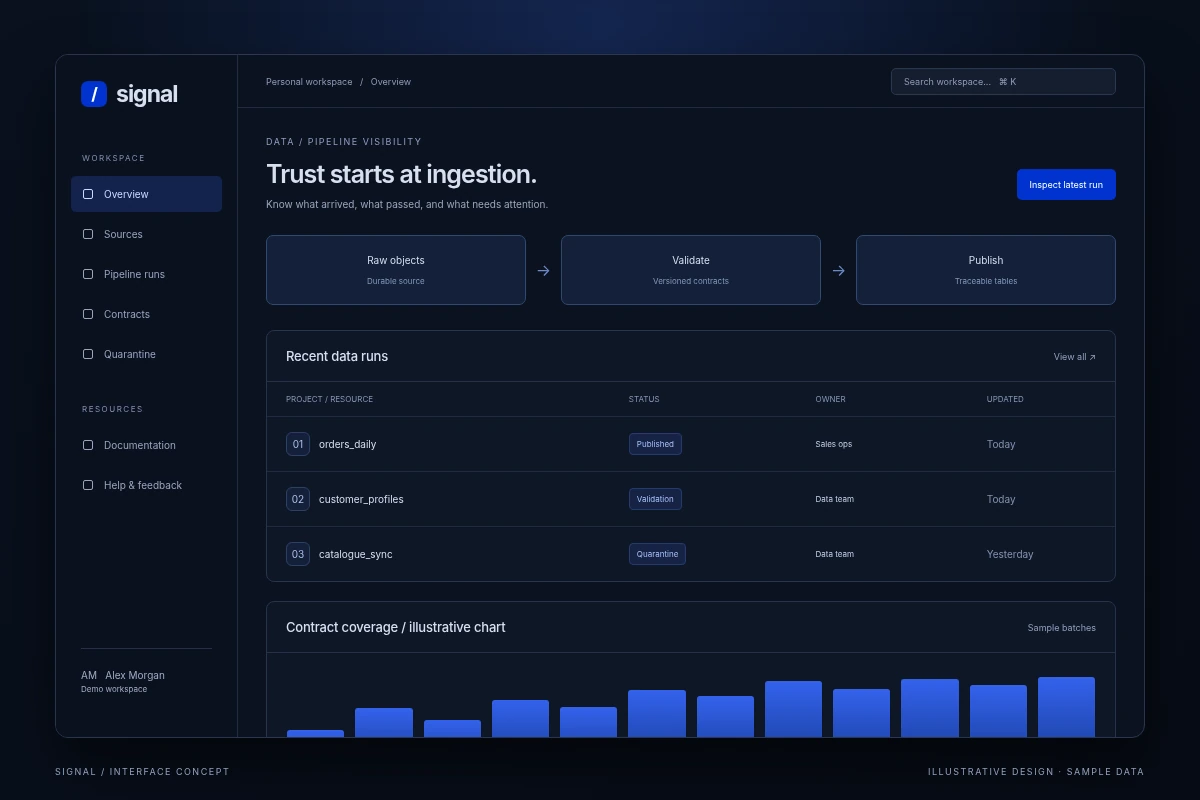
Signal is a data-platform concept for bringing external datasets into an analytics-ready store. The emphasis is on trustworthy handoffs: an analyst should know what arrived, what failed validation and whether a published table is complete.
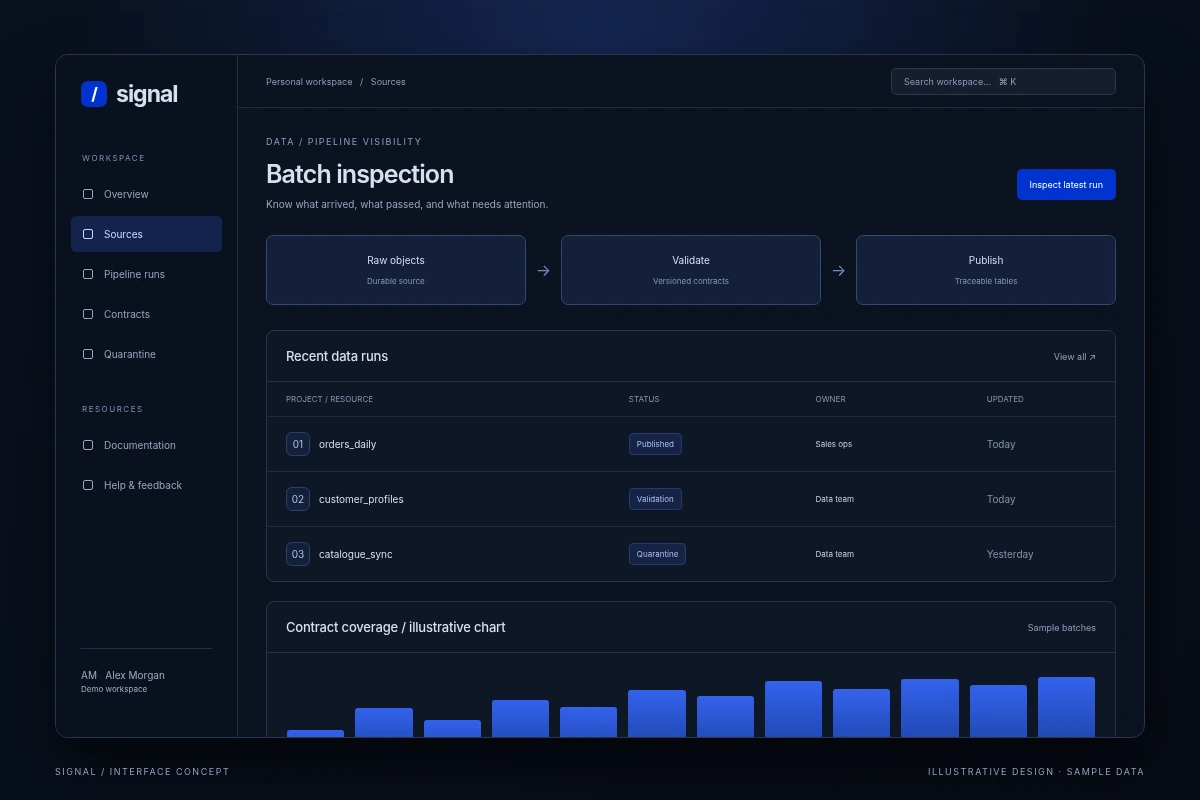
The sample interface visualises batch runs and validation results. Its numbers are interface fixtures, not reported customer outcomes.
The problem
External data changes without warning. A renamed column or duplicate batch can quietly break a report even when the ingestion job appears to have completed.
The pipeline must distinguish transport success from data quality, preserve enough source context for diagnosis and make reprocessing safe.
The solution
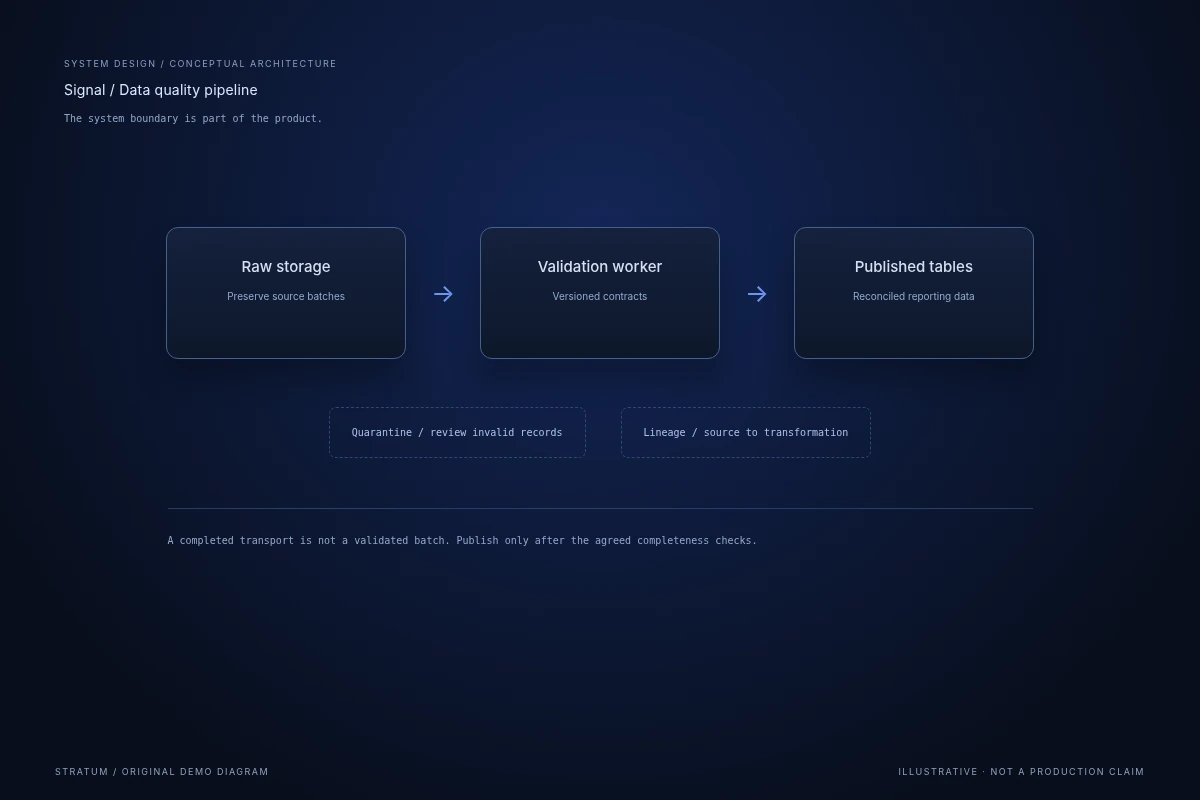
The design separates raw ingestion, validation and publication. Incoming batches receive stable identifiers and are stored before transformation. A contract check routes rejected records to a reviewable quarantine instead of silently dropping them.
Validated output is published only after the batch meets the relevant completeness rules. Runs keep lineage from source object through transformation version to the published table.
Ownership, made explicit
My contribution
- Data contracts: define required fields, allowed types and explicitly handled schema changes.
- Pipeline stages: implement the proposed raw, validated and published boundaries with independently observable run states.
- Recovery: design idempotent reprocessing and versioned transformations.
- Quality reporting: make rejected records, rule failures and batch completeness visible to analysts.
- Collaboration: business definitions belong to the analyst; the engineering role turns them into testable contracts.
Architecture
Source objects enter durable raw storage. A Python validation worker checks contracts and writes either a quarantine result or a normalised batch. A publication step updates PostgreSQL reporting tables with a recorded run identifier.
The proposed architecture favours batch transparency over an unnecessary real-time promise. Scheduling frequency should follow a documented reporting requirement.
Key features
Contract checks
Schema and completeness checks are versioned and tied to the batch that was evaluated.
Quarantine workflow
Invalid records remain inspectable, with rule-level explanations and a defined reprocessing path.
Run lineage
Published tables can be traced to source objects and transformation revisions.
Challenges & trade-offs
Strict validation protects downstream consumers but may delay useful data. The right policy depends on the consequence of a missing or malformed field; not every rule should block the whole batch.
Backfills also need resource limits and version-aware behaviour. A replay should not overwrite an already published result without an explicit policy.
Results & impact
The concept establishes the proposed data flow, ownership boundaries and a recovery strategy. It does not claim improved reporting accuracy or reduced processing cost.
A real implementation should measure freshness, rejected-record rates and reconciliation against source totals, using agreed definitions.
Screenshots
Technology stack
Cloud infrastructure and managed platform services.
DocumentationReproducible application builds and runtime environments.
DocumentationRelational modelling, transactions and query planning.
DocumentationData transformations, automation and retrieval services.
Documentation